
TL;DR: Prompt injection is the number one risk on the OWASP Top 10 for LLM Applications for the second consecutive edition, and the data backs up why it stays there: 83 percent of organizations plan to deploy agentic AI, but only 29 percent feel prepared to secure it, and separate research puts the share of production AI deployments vulnerable to at least one prompt injection technique at roughly 73 percent. Testing for it after launch is too late. It has to be part of the same pipeline that tests everything else the AI agent does.
Quick answers
What is prompt injection in LLM security testing?
Prompt injection is an attack where user input or content the model reads, a document, a webpage, an email, contains instructions the model follows as if they came from its system prompt or its developer, because large language models process instructions and untrusted data in the same channel with no hard separation between the two.
What is the difference between direct and indirect prompt injection?
Direct prompt injection is a user typing an attack straight into the input, for example asking a chatbot to ignore its prior instructions and reveal its system prompt. Indirect prompt injection hides the same kind of instruction inside content the model processes later, a webpage it summarizes, a document it retrieves, an email it reads, so the attacker never has to interact with the model directly at all.
What is jailbreaking in LLM security testing?
Jailbreaking is any technique that gets a model to ignore its safety training and produce a response it was built to refuse: role-play personas without safety constraints, hypothetical or fictional framing, multi-turn escalation that builds up to the harmful request over several messages, or encoding the ask so a filter does not recognize it. It overlaps with prompt injection since many jailbreaks use an injection technique to work, but the goal is different. Prompt injection hijacks what the model does, jailbreaking gets the model to say or generate something it was trained not to.
What is AI red-teaming?
Red-teaming is deliberately attacking an AI system with the same techniques a real attacker would use, prompt injection, jailbreak attempts, encoding tricks, multi-turn manipulation, to find its weaknesses before it ships. In LLM security testing it ranges from broad automated scans on every release to deep, adaptive, often human-led attacks reserved for major releases.
Can automated red-teaming replace manual security review for LLM applications?
No. Automated tools are what make red-teaming repeatable in CI/CD: broad scanners catch known attack patterns on every build, and regression suites catch when a fix breaks. Neither is good at the genuinely novel attack a human red-teamer would think to try, or at judging whether a borderline response is an acceptable business risk. Layer both.
What is guardrail validation?
Guardrail validation is testing whether the safety layer sitting in front of or behind a model, a rules engine, a classifier, a regex filter, actually blocks what it is configured to block without also blocking legitimate requests. It is a different question from red-teaming: red-teaming asks whether an attack gets through the system as a whole, guardrail validation asks whether one specific safety layer is doing its job.
OWASP Top 10 for Large Language Models (LLM01: Prompt Injection Breakdown)
The OWASP Top 10 for LLM Applications lists ten categories of risk specific to LLM-powered systems, and prompt injection has held the top spot, LLM01, across both the current and prior edition. The other nine matter for a full security review: LLM02 Sensitive Information Disclosure, LLM03 Supply Chain, LLM04 Data and Model Poisoning, LLM05 Improper Output Handling, LLM06 Excessive Agency, LLM07 System Prompt Leakage, LLM08 Vector and Embedding Weaknesses, LLM09 Misinformation, and LLM10 Unbounded Consumption.
Why Is Prompt Injection Ranked Number One?
Prompt injection sits at number one because it is the entry point for several of the others. An attacker who successfully injects instructions can often use that access to trigger excessive agency (LLM06), getting an agent to call a tool or take an action it should not, or to leak the system prompt itself (LLM07). Testing prompt injection in isolation misses that chain reaction. A serious test plan checks what an agent can actually do once an injection succeeds, not just whether the injection is possible.
Direct vs Indirect Prompt Injection: Vulnerability Mechanics
Direct injection is the easier of the two to test for, because the attacker and the tester are doing the same thing: typing adversarial input into the same box a real user would use. Classic examples that still work against under-defended systems include instructing the model to ignore prior instructions, asking it to role-play a persona without safety constraints, or encoding the attack (base64, leetspeak, translated into another language) to slip past a keyword filter.
Indirect injection is the mechanism behind most of the incidents that make headlines, because it does not require tricking a human user into typing anything malicious. Research tracking these incidents puts web-based indirect injection at close to 40 percent of all reported LLM security incidents. A support agent that summarizes incoming emails, a coding assistant that reads a README from an untrusted repository, or a research agent that browses the open web are all exposed the moment any of that content can carry hidden instructions, invisible text, HTML comments, metadata, that the model treats as commands.
This is why test coverage has to include the data sources an agent reads, not just the chat input box. If an AI agent's tools include fetching a webpage, reading a file, or querying a database, every one of those is a place an indirect injection can enter, and a security test plan should treat each one as its own attack surface.
Automated Red-Teaming Pipelines: Simulating Adversarial Attacks in CI/CD
Manual red-teaming does not scale to the release cadence most AI products ship on now, which is why the practical pattern has become layered automation rather than one tool doing everything. A useful way to think about it, per security teams building these pipelines on GPU infrastructure, is broad coverage, then regression, then depth:
- Broad scanning: tools like Garak run wide, static probes for jailbreaks, encoding attacks, and known prompt injection patterns across a large catalog of attack templates. Run this nightly or on every release, and archive results so a regression is visible over time.
- Regression testing: tools like Promptfoo run a defined set of attacks and expected-safe outputs against every pull request, the same way a unit test suite runs, so a change that reopens a previously fixed vulnerability fails the build instead of shipping.
- Deep exploitation: tools like Microsoft's PyRIT handle multi-turn, adaptive attacks, including crescendo-style attacks that build up to a harmful request over several turns instead of asking for it directly. This layer is closer to real red-teaming and usually runs less often, before a major release rather than on every commit.
- Runtime filtering: input and output scanning for PII and injection patterns at the request level, as a last line of defense for whatever the earlier layers did not catch before a release.
The reason to wire any of this into CI/CD is the same reason teams run any other automated test suite: catching a regression the day it is introduced costs a code review comment, catching it after release costs an incident.
Guardrail Validation: Testing NeMo Guardrails, Llama Guard, and Custom Regex Filters
Guardrails and red-teaming test different things, and conflating them is a common gap in security test plans. Red-teaming asks whether an attack succeeds. Guardrail validation asks whether the safety layer sitting in front of, or behind, the model actually does what it is configured to do, on both attack input and completely normal input.
NVIDIA's NeMo Guardrails defines programmable rails using its own Colang scripting language, rule-based checks backed by an LLM fallback for cases the rules do not cover cleanly. Testing it means confirming both directions: that a defined-unsafe topic or action is actually blocked, and, just as important, that a legitimate request phrased slightly unusually is not falsely blocked. A guardrail that blocks half of real user requests to stop the rare attack is not a passing test, it is a different failure.
Llama Guard works differently, as a classifier model sitting in the pipeline that scores a message against defined harm categories before it reaches the main model or before a response reaches the user. Testing a classifier-based guardrail means building a labeled test set of known-safe and known-unsafe messages, including ones deliberately close to the decision boundary, and tracking false positive and false negative rates as the guardrail model or its thresholds change, not just the day it is first deployed.
Custom regex or keyword filters are the least reliable layer and the easiest to test, which is exactly why they should never be the only layer. They catch the exact string an engineer thought to block and almost nothing else; a single encoding trick, a synonym, or a translated phrase gets past most of them. Treat regex filters as a cheap first pass, not a security control, and validate that assumption directly by running the same attack corpus used against the other layers through the regex filter alone. If it catches most of what Garak or Promptfoo catch, that is a sign the test corpus is too narrow, not that the regex filter is unusually good.
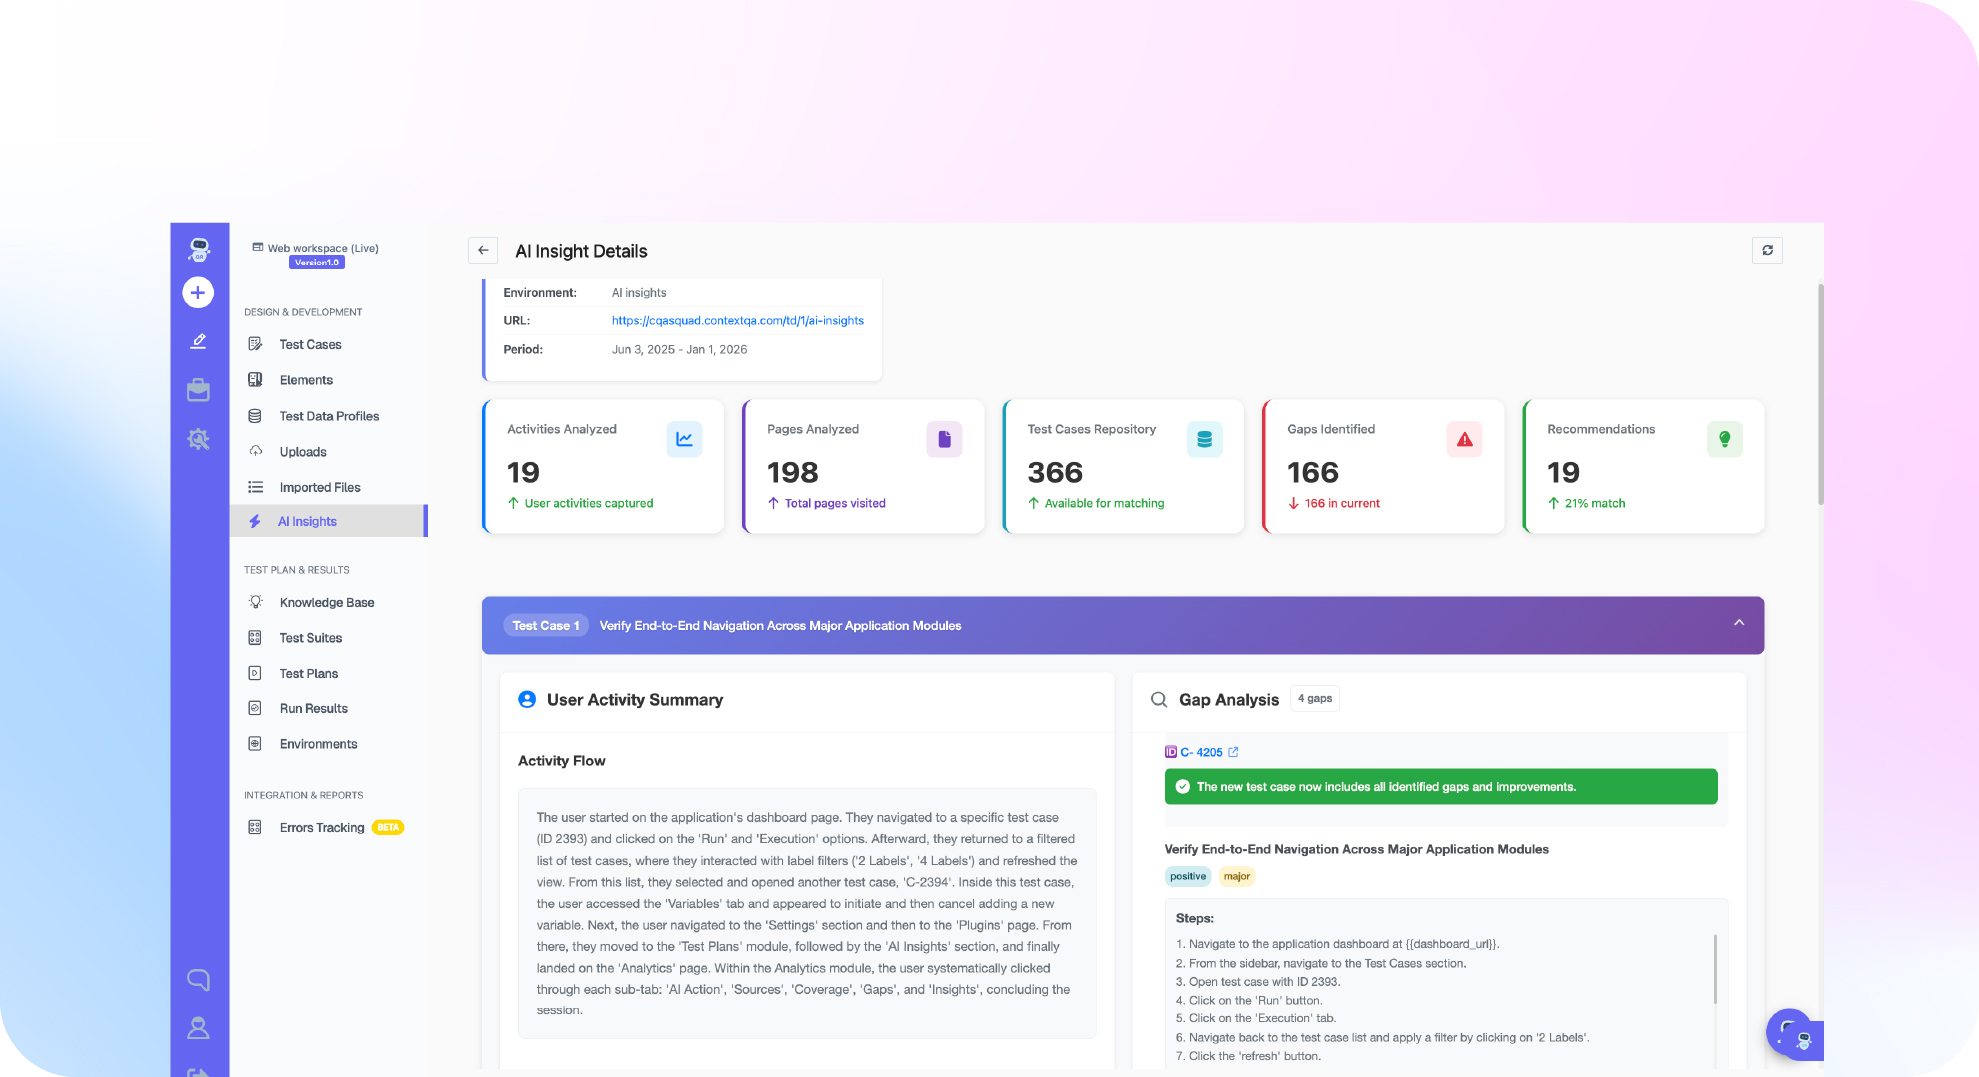
Testing for jailbreaks and prompt injection is part of validating an AI agent before it goes live, not a separate security project bolted on afterward. ContextQA's AI agent testing includes red-teaming for jailbreaks and prompt injection alongside the same evaluation layer that checks an agent's everyday behavior, so a regression in either shows up in the same test run. See it on a 15-minute demo.
Frequently Asked Questions
Is prompt injection even fixable, or just manageable?
Manageable is the honest answer today. Because instructions and data share the same input channel in current LLM architectures, no defense is complete. OWASP's own guidance frames mitigation as defense in depth, combining input validation, output filtering, privilege restriction, and human review for sensitive actions, rather than a single fix that closes the class of vulnerability.
How often should an AI agent be red-teamed?
Broad automated scans belong in every release pipeline, the same as any other automated test. Deeper, multi-turn red-teaming and any manual review are usually scheduled around major releases or a set cadence, monthly or quarterly, since they are more resource-intensive and target novel attacks rather than known patterns.
Do guardrails replace the need for red-teaming?
No, they are complementary layers. Red-teaming finds what an attack can get through; guardrails are one of the things standing in its way. Testing only the guardrail in isolation, without also attacking the full system, misses failures that happen when an attack bypasses the guardrail entirely through a channel it was never configured to watch.
Bottom line
The organizations Cisco surveyed are not wrong to be nervous: shipping an AI agent without security testing built into the same pipeline that tests its functionality is shipping blind to the exact category of risk regulators and customers are now asking about directly. Prompt injection testing, layered red-teaming, and guardrail validation are not a separate track from functional QA anymore, they are functional QA for a system whose main input is also its main attack surface. For a deeper look at the tools available for this, see our guide to LLM testing tools and frameworks in 2026.
Prompt injection, jailbreak, and guardrail testing should not be a separate audit bolted onto a release. See how ContextQA's security testing runs these checks alongside your everyday AI agent tests, or book a 15-minute demo to see it against your own agent.